FlexSpIM: An Event-Based Digital Compute-In-Memory Accelerator with Flexible Operand Resolution and Layer-Wise Hybrid Stationarity
By Nicolas Chauvaux, Adrian Kneip and Charlotte Frenkel
Delft University of Technology (TU Delft), Delft, The Netherlands
Abstract
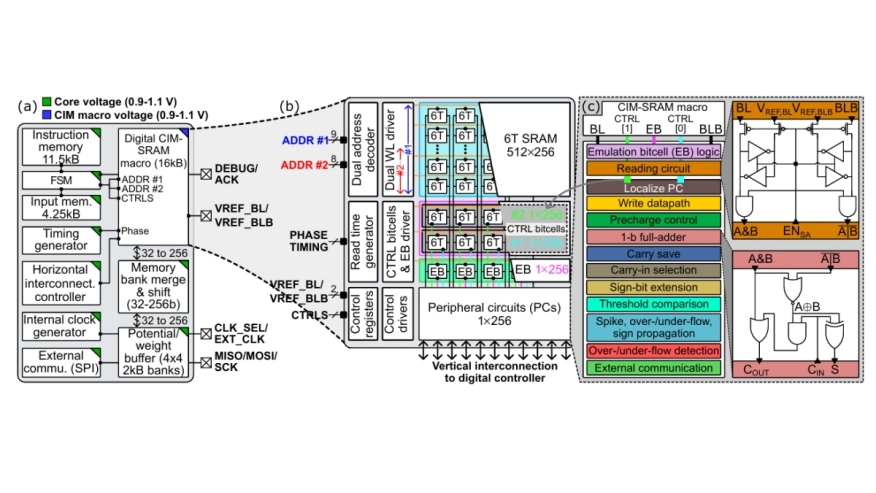
Compute-in-memory (CIM) accelerators for spiking neural networks (SNNs) offer a promising solution for achieving μs-level inference latency and ultra-low energy in edge vision applications. However, their limited flexibility at both circuit and system levels restricts their deployment across diverse workloads. This work introduces FlexSpIM, a digital CIM architecture supporting arbitrary operand resolution and shape within a unified storage for weights and neuron states (i.e., membrane potentials). These circuit-level capabilities enable a layer-level hybrid weight- and output-stationary dataflow, maximizing operand reuse and reducing costly on- and off-chip data movement during SNN execution. Measurement results from a fabricated FlexSpIM prototype in 40-nm CMOS demonstrate competitive 1-bit-normalized energy efficiency and higher throughput compared with prior fixed-precision digital CIM-based SNN accelerators, while providing bitwise resolution reconfiguration. Evaluated on the IBM DVS gesture dataset, FlexSpIM achieves 95.8% accuracy while enabling up to 45% energy and 52% latency reductions in large-scale systems compared with fixed stationarity approaches.
Index Terms—Digital compute-in-memory, spiking neural net works, flexible operand resolution, hybrid-stationary dataflow.
To read the full article, click here
Related Semiconductor IP
- MACsec Engine optimized for 10Base-T1S/T1L applications
- Dual Port, Voltage Scaling Register File Compiler on GF22FDX+
- Single Port, Voltage Scaling, High Speed SRAM Memory Compiler on GF22FDX+
- I3C Full Controller / Target
- I3C HCI Host Controller
Related Articles
- Peregrino: A Full-Hardware Accelerator for the Complete Falcon Post-Quantum Digital Signature Scheme on Resource-Constrained Edge Devices
- Assessing Design Space for the Device-Circuit Codesign of Nonvolatile Memory-Based Compute-in-Memory Accelerators
- 3+ ways to design reconfigurable algorithm accelerator in IP block
- RAID6 accelerator in a PowerPC IOP SOC
Latest Articles
- PULSAR-V: I/O-Aware Post-Update Attestation for RISC-V
- PVTSizing 2.0: A Fast and Reliable Analog Circuit Sizing Operator for Agentic EDA Workflows
- An Agentic Python Framework for LLM-Driven UVM Testbench Synthesis with Closed-Loop Compiler Feedback
- Reconfiguring System-Level Protection Through Bounded Delegation in RISC-V MCUs
- SkipLane: Write-Once, Conflict-Free Accumulation for Zero-Skipping CNN Engines on FPGAs