Agentic AI for Heterogeneous System Design Across Chip, Scale-Up, and Scale-Out Domains
By Murali Emani 1, Kashyap R Manjusha 2
1 Argonne National Laboratory, IL, USA
2 University of Illinois Urbana-Champaign, IL, USA
Abstract
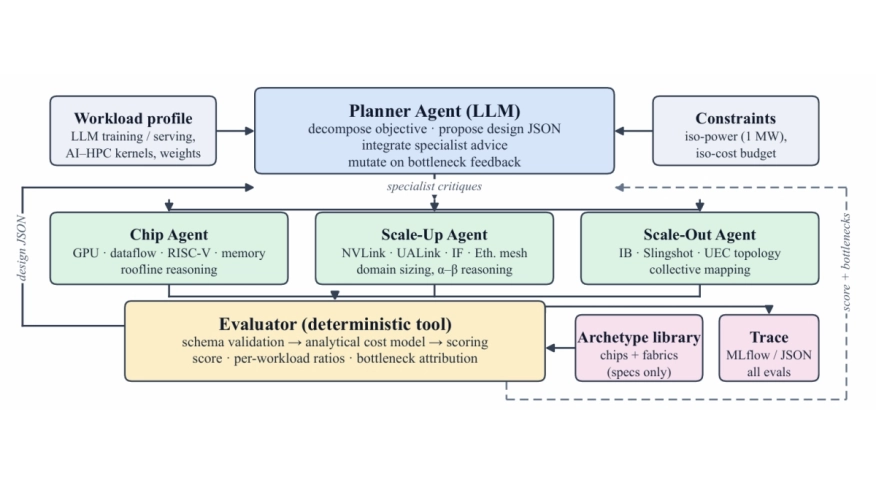
The design space of modern AI/HPC systems has expanded rapidly across compute architectures, including GPUs, dataflow processors, and RISC-V accelerators; memory tech- nologies, including HBM, GDDR, and SRAM; and interconnects such as NVLink, UALink, Infinity Fabric, InfiniBand, Slingshot, and Ultra Ethernet. No single architecture is optimal across LLM training, LLM serving, and AI-coupled HPC workloads, while the resulting combinatorial design space is too large for manual exploration. We present ArchAgent, a hierarchical multi- agent framework in which an LLM-based planner decomposes system design into chip, scale-up, and scale-out subproblems, each handled by specialist agents. A deterministic analytical evaluator closes the loop, ensuring that all performance estimates are derived from analytical models rather than generated by the LLM. On a mixed AI+HPC workload under a 1 MW power budget, ArchAgent discovers heterogeneous designs that achieve a 1.93x weighted geometric mean speedup over a homogeneous GPU baseline, while requiring only 18 evaluations compared with 100 evaluations for hill climbing, which achieves 1.65x speedup.
To read the full article, click here
Related Semiconductor IP
- I3C Full Controller / Target
- I3C HCI Host Controller
- USB-C Power Delivery IP Core
- ACU100 Audio Computing IP
- PDM Modulator PCM to PDM Conversion IP
Related Articles
- Open-Source Design of Heterogeneous SoCs for AI Acceleration: the PULP Platform Experience
- David vs. Goliath: Can Small Models Win Big with Agentic AI in Hardware Design?
- The Quest for Reliable AI Accelerators: Cross-Layer Evaluation and Design Optimization
- RFChipAgent: Multi-Agentic AI Flow for Analog/RF Chip Design
Latest Articles
- Reconfiguring System-Level Protection Through Bounded Delegation in RISC-V MCUs
- SkipLane: Write-Once, Conflict-Free Accumulation for Zero-Skipping CNN Engines on FPGAs
- Priority-Aware Deficit Round Robin for AXI4 Bandwidth Fairness in ASAP-7nm Process
- Atik: A Shared-Mesh Transformer Accelerator for RISC-V
- GSPIM: A Temporal-Locality-Aware 4D Gaussian Splatting Accelerator with Polymorphic PIM and Multi-Frame Rendering Dataflow