OpenEye: A Scalable Open-Source Hardware Accelerator for DNNs
By Denis Lebold 1 and Hendrik Wöhrle 1,2
1 University of Duisburg-Essen, Germany
2 Fraunhofer Institute for Microelectronic Circuits and Systems, Germany
Abstract
The increasing computational complexity of deep neural network inference poses significant challenges for efficient hardware acceleration on embedded platforms, particularly with respect to resource consumption and scalability. This work presents OpenEye, a scalable and sparsity-aware FPGA-based hardware accelerator designed to efficiently execute common neural network operations such as convolutions, dense layers, and pooling.
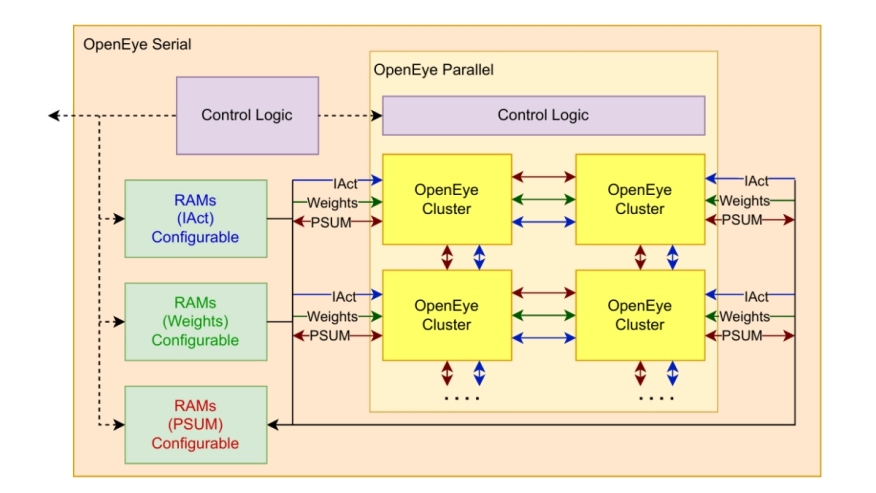
OpenEye is based on a highly parameterizable architecture composed of clusters of processing elements interconnected by a streaming-based dataflow. The paper provides a detailed explanation of the internal operation of the accelerator, including data movement, buffering strategies, control logic, and the coordination between clusters and PEs. The architecture natively supports sparse weights and activations, enabling the efficient processing of sparse data without unnecessary computations or memory accesses.
A key design property of OpenEye is its scalability: the number of clusters and processing elements can be varied to adapt the accelerator to different performance and resource constraints. The design achieves a near-linear scaling of routing and interconnect overhead with increasing PE counts, which is essential for maintaining efficiency on large FPGA devices.
To evaluate scalability across different design points, multiple OpenEye configurations with varying cluster and PE sizes were implemented on a Xilinx ZU19EG FPGA. Representative neural network operations, including convolutional, fully connected, and pooling layers, were used to analyze resource utilization, execution latency, and scalability behavior. The results show favorable trade-offs between performance and resource consumption across the explored configurations.
Keywords: Hardware Accelerator, DNN, Open-Source, Scalability
To read the full article, click here
Related Semiconductor IP
- Mesochronous Bridge for PCIe/CXL
- AI-native GPU
- OpenGMSL Verification IP
- OpenGMSL Leaf IP
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
Related Articles
- Heterogeneous SoC Integrating an Open-Source Recurrent SNN Accelerator for Neuromorphic Edge Computing on FPGA
- Open-source hardware for embedded security
- SPAD: Specialized Prefill and Decode Hardware for Disaggregated LLM Inference
- RISC-V Based TinyML Accelerator for Depthwise Separable Convolutions in Edge AI
Latest Articles
- FlexSpIM: An Event-Based Digital Compute-In-Memory Accelerator with Flexible Operand Resolution and Layer-Wise Hybrid Stationarity
- MeshKV: A Network-on-Chip KV Cache Fabric for Scalable Transformer Decoding Accelerators
- Analog Pin Directionality as an Exfiltration Attack Surface in Mixed-Signal ICs
- SIMT-Aware Lockstep Verification and Functional-Coverage Closure Methodology for an Open-Source RISC-V GPGPU: A UVM 1.2 Environment
- Efficient Hardware Information-Flow Tracking for Pre-Silicon Security Testing