ZTA-Q: an Open-source RISC-V Platform for Accurate Quantized CNN Inference
By Yike Li ∗, Ajay Kumar M ∗, Vishnu PS ∗, Dimitrios S. Nikolopoulos ‡, Bo Ji ‡, Hans Vandierendonck §, Deepu John ∗
∗ University College Dublin, Ireland
‡ Virginia Tech, USA
§ Queen’s University Belfast, UK
Abstract
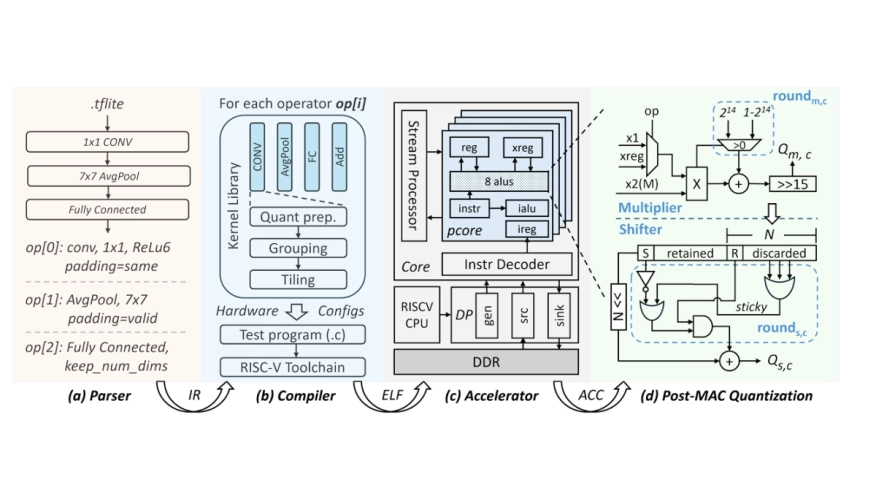
Low-precision inference is widely adopted in edge AI to reduce computational cost and memory footprint. However, existing open-source accelerator platforms provide limited end-to-end support for CNNs following the standard TensorFlow Lite integer inference scheme. This paper presents ZTA-Q, an open-source RISC-V-based platform that enables accurate deployment of TensorFlow Lite INT8 models. In addition to extending operator support, ZTA-Q provides a configurable post-processing datapath for studying how circuit-level approximations, including reduced multiplier precision, shared shift scaling, and simplified rounding, affect model accuracy. The proposed system is implemented on a Digilent Arty A7-100T FPGA and operates at 83.3 MHz. Evaluations on representative CNN models show that with LUT, register, and DSP overheads of 26.3%, 12.6%, and 150%, respectively, ZTA-Q limits the degradation in both top-1 and top-5 accuracy to within 0.25 percentage points.
Index Terms—Deep Learning, Hardware accelerators, RISC-V, Quantization, FPGA
To read the full article, click here
Related Semiconductor IP
Related Articles
- Open-Source Design of Heterogeneous SoCs for AI Acceleration: the PULP Platform Experience
- An Open-Source Approach to Developing a RISC-V Chip with XiangShan and Mulan PSL v2
- A RISC-V Multicore and GPU SoC Platform with a Qualifiable Software Stack for Safety Critical Systems
- Leveraging RISC-V as a Unified, Heterogeneous Platform for Next-Gen AI Chips
Latest Articles
- PVTSizing 2.0: A Fast and Reliable Analog Circuit Sizing Operator for Agentic EDA Workflows
- An Agentic Python Framework for LLM-Driven UVM Testbench Synthesis with Closed-Loop Compiler Feedback
- Reconfiguring System-Level Protection Through Bounded Delegation in RISC-V MCUs
- SkipLane: Write-Once, Conflict-Free Accumulation for Zero-Skipping CNN Engines on FPGAs
- Priority-Aware Deficit Round Robin for AXI4 Bandwidth Fairness in ASAP-7nm Process