Towards Delta Aware Training: Efficient DNN Weight Storage for Resource-Constrained FPGAs
By David Peter Federl, Lukas Einhaus, Andreas Erbslöh, Gregor Schiele
University Duisburg-Essen, Germany
Abstract
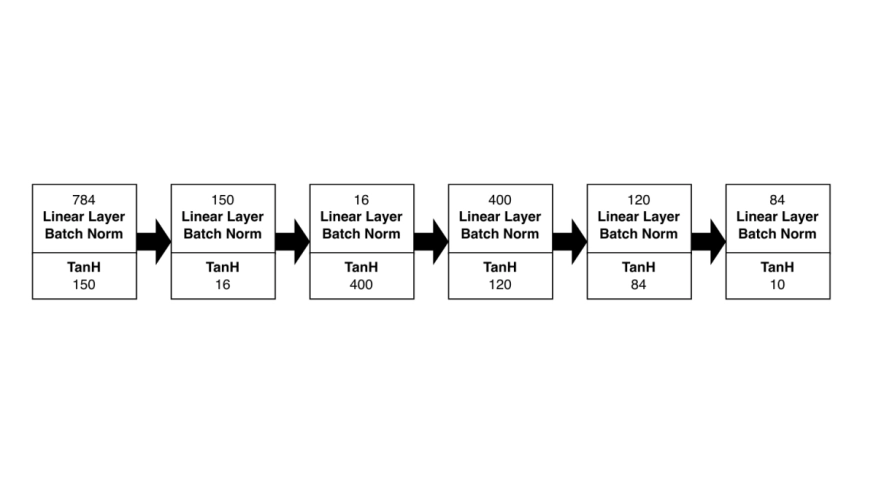
The deployment of embedded deep neural networks on resource-constrained field programmable gate arrays (FPGAs) is challenging due to limited memory and computational capacities. We introduce a new compression technique to reduce the memory footprint by saving weights in deltas with lower bitwidth and training the network to cope with compressed deltas. Two delta schemes are investigated: consecutive deltas and deltas with a fixed-reference value. We evaluate both on the FashionMNIST data set with a multi-layer-perceptron. The results indicate that fixed-reference delta compression outperforms the consecutive variant, achieving a validation accuracy of approximately 78.6 %, with 4 bit weight deltas, representing an accuracy loss of roughly 8.3 % compared to a fixed-point network with 8 bit. Our specialized hardware accelerator with a delta-compressed multiply-and-accumulate operator compresses weights by nearly 50 % and achieves a maximum throughput of 7.992M MACs/s on an AMD Spartan-7 S15 FPGA.
Keywords: embedded deep neural networks, resource-constrained, field programmable gate array, hardware accelerator, fixpoint-arithmetic, quan tization aware training, weight compression
To read the full article, click here
Related Semiconductor IP
- Highly scalable inference NPU IP for next-gen AI applications
- NPU IP Core for Edge
- 4-/8-bit mixed-precision NPU IP
- AI inference processor IP
- 4/8-bit mixed-precision NPU IP
Related Articles
- Leveraging FPGAs for Homomorphic Matrix-Vector Multiplication in Oblivious Message Retrieval
- A 16 nm 1.60TOPS/W High Utilization DNN Accelerator with 3D Spatial Data Reuse and Efficient Shared Memory Access
- PDF: PUF-based DNN Fingerprinting for Knowledge Distillation Traceability
- VMXDOTP: A RISC-V Vector ISA Extension for Efficient Microscaling (MX) Format Acceleration
Latest Articles
- LLM Agent-Based Design of RISC-V CPUs with FPGA-in-the-Loop Evaluation
- Automated Multi-Line Bug Repair Using Model Checker Aided LLMs: A Case Study on RISC-V Processors
- Cryogenic Recharacterization of a Commercial 22 nm FD-SOI Foundry Standard-Cell Library
- A 105 MS/s 4.18 nJ/inference 0.765 mm² Mixed-Signal Streaming ML Engine for Wireless Baseband in 12LP+ FinFET
- Agentic AI for Heterogeneous System Design Across Chip, Scale-Up, and Scale-Out Domains