A Heterogeneous Neural Network Accelerator for End-to-End Multitask RF Signal Recognition
By Zhifan Song, Haralampos-G. Stratigopoulos, and Hassan Aboushady
Sorbonne University, CNRS, LIP6, Paris, France
Abstract
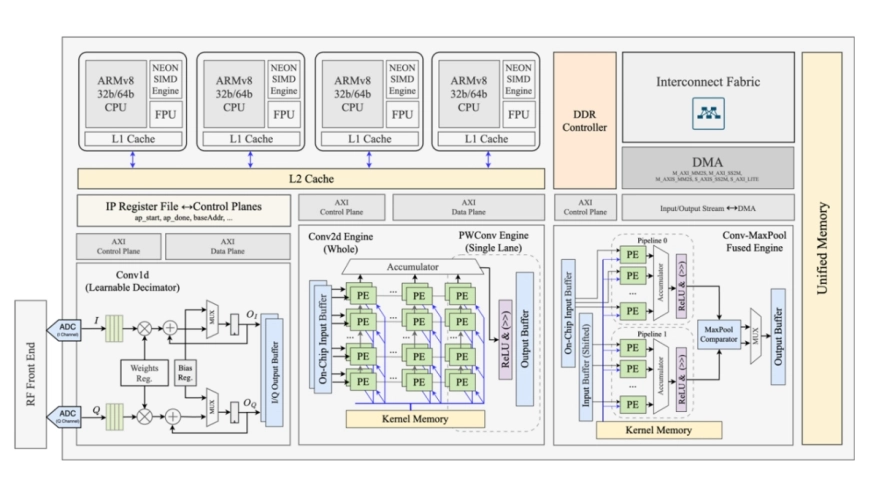
This paper presents a heterogeneous neural network accelerator for multi-task RF signal recognition, supporting automatic modulation recognition (AMR), hardware-Trojan covert channel (HT-CC) detection, and GNSS jamming classification. We introduce a compact attention-enhanced convolutional neural network (CNN) combined with LSDec, a learnable streaming decimator that enables adaptive temporal downsampling and flexible input lengths. The hardware architecture integrates a novel dual-pipeline, fused convolution-pooling engine with DMA-based streaming to minimize memory traffic and latency. Co-execution scheduling on the accelerator and SIMD-optimized CPU kernels reduces hardware resource usage while preserving high performance and task-level flexibility. Across three datasets, the proposed system achieves ≥ 99% average accuracy above 4 dB Signal-to-Noise Ratios (SNRs) on the RadioML2018 dataset for AMR, 90% on the HT-CC dataset, and 99.5% on the GNSS-Jamming dataset. The accelerator sustains an end-to-end inference latency of 98 μs per frame, demonstrating its effectiveness for low-power, latency-critical multi-task spectrum-intelligence applications on embedded and edge devices.
To read the full article, click here
Related Semiconductor IP
- LPDDR6 PHY
- UMC 55nm ULP 3.3V Temperature Sensor
- High-Throughput Multi-Channel DMA Controller
- Configurable Multi-Channel DMA Controller
- Fixed-Channel Multi-Channel DMA Controller
Related Articles
- SNAP-V: A RISC-V SoC with Configurable Neuromorphic Acceleration for Small-Scale Spiking Neural Networks
- An FPGA-Based SoC Architecture with a RISC-V Controller for Energy-Efficient Temporal-Coding Spiking Neural Networks
- AceleradorSNN: A Neuromorphic Cognitive System Integrating Spiking Neural Networks and Dynamic Image Signal Processing on FPGA
- MeshKV: A Network-on-Chip KV Cache Fabric for Scalable Transformer Decoding Accelerators
Latest Articles
- Automated Multi-Line Bug Repair Using Model Checker Aided LLMs: A Case Study on RISC-V Processors
- Cryogenic Recharacterization of a Commercial 22 nm FD-SOI Foundry Standard-Cell Library
- A 105 MS/s 4.18 nJ/inference 0.765 mm² Mixed-Signal Streaming ML Engine for Wireless Baseband in 12LP+ FinFET
- Agentic AI for Heterogeneous System Design Across Chip, Scale-Up, and Scale-Out Domains
- Minimum RISC-V: Maximum FPGA Efficiency