New AXI Scatter-Gather DMA Core Transfers Streaming Data to/from System Memory
February 8, 2021
Data processing accelerators are often designed with streaming interfaces and are meant for continuous flow through a custom hardware processing pipeline. Such cores include engines for compression, cryptography, or packet processing. A custom hardware pipeline built of such cores would be similar to this:

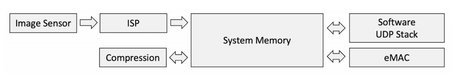
Sometimes, though, designers want the data processing accelerator to store or retrieve its data to or from the systems memory rather than directly transferring data to or from the next or preceding pipeline stage. So, our example custom hardware pipeline now transforms to something like this:
To read the full article, click here
Related Semiconductor IP
- AXI4 to/from AXI4-Stream Scatter-Gather DMA
- AXI4-Stream to/from AXI Memory Map – 2 DMA Channels - Control by SGL Commands Streams
Related Blogs
- The silicon behind Android
- Nice Core ARM; Pity About Intel MDF
- ARM Cortex-A15 - does this processor IP core need a new category ... Superstar IP?
- ARM furthers its "cover the earth" strategy with introduction of R5 and R7 core variants for fast, real-time, deterministic SoC applications
Latest Blogs
- Automated, Faster Specification to Sign-Off with IDS-AI
- NovaTech Automation Crius PIU: Bringing Conventional Instrument Transformers onto the IEC 61850 Process Bus
- Single Pair Ethernet and TSN: The In-Robot Network Behind the Next Humanoid Robots
- A design path to success exists for ultra-low-voltage SoCs
- Where Routine Flow Ends Veriest Formal Expertise Begins