SynapticCore-X: A Modular Neural Processing Architecture for Low-Cost FPGA Acceleration
By Arya Parameshwara, Department of Electronics and Communication, PES University, Bangalore, India
Abstract
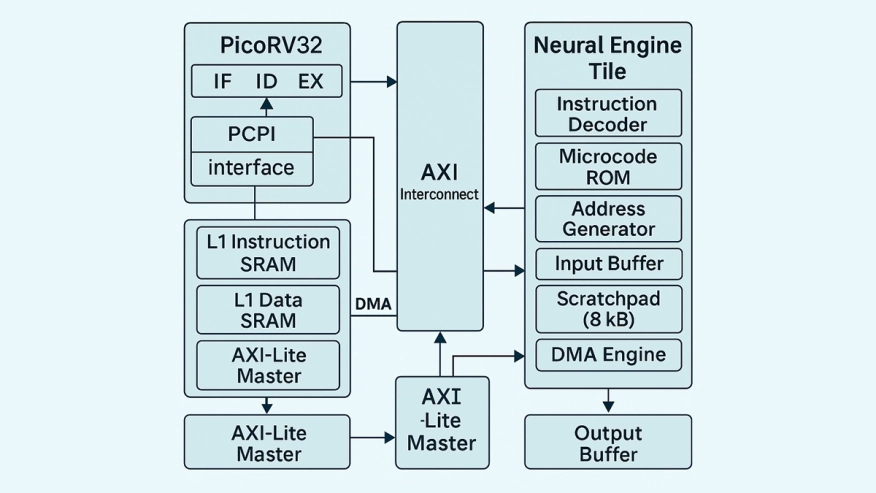
This paper presents SynapticCore-X, a modular and resource-efficient neural processing architecture optimized for deployment on low-cost FPGA platforms. The design integrates a lightweight RV32IMC RISC-V control core with a configurable neural compute tile that supports fused matrix, activation, and data-movement operations. Unlike existing FPGA accelerators that rely on heavyweight IP blocks, SynapticCore-X provides a fully open-source SystemVerilog microarchitecture with tunable parallelism, scratchpad memory depth, and DMA burst behavior, enabling rapid exploration of hardware-software co-design trade-offs. We document an automated, reproducible Vivado build pipeline that achieves timing closure at 100 MHz on the Zynq-7020 while consuming only 6.1% LUTs, 32.5% DSPs, and 21.4% BRAMs. Hardware validation on PYNQ-Z2 confirms correct register-level execution, deterministic control-path behavior, and cycle-accurate performance for matrix and convolution kernels. SynapticCore-X demonstrates that energy-efficient NPU-like acceleration can be prototyped on commodity educational FPGAs, lowering the entry barrier for academic and open-hardware research in neural microarchitectures.
To read the full article, click here
Related Semiconductor IP
- NPU
- RISC-V-Based, Open Source AI Accelerator for the Edge
- NPU IP
- Highly scalable inference NPU IP for next-gen AI applications
- 4-/8-bit mixed-precision NPU IP
Related Articles
- AceleradorSNN: A Neuromorphic Cognitive System Integrating Spiking Neural Networks and Dynamic Image Signal Processing on FPGA
- Finding the Right Processing Architecture for AES Encryption
- A Real-Time Image Processing with a Compact FPGA-Based Architecture
- Using parallel FFT for multi-gigahertz FPGA signal processing
Latest Articles
- Automated Multi-Line Bug Repair Using Model Checker Aided LLMs: A Case Study on RISC-V Processors
- Cryogenic Recharacterization of a Commercial 22 nm FD-SOI Foundry Standard-Cell Library
- A 105 MS/s 4.18 nJ/inference 0.765 mm² Mixed-Signal Streaming ML Engine for Wireless Baseband in 12LP+ FinFET
- Agentic AI for Heterogeneous System Design Across Chip, Scale-Up, and Scale-Out Domains
- Minimum RISC-V: Maximum FPGA Efficiency